
ZFS Dataset Tuning
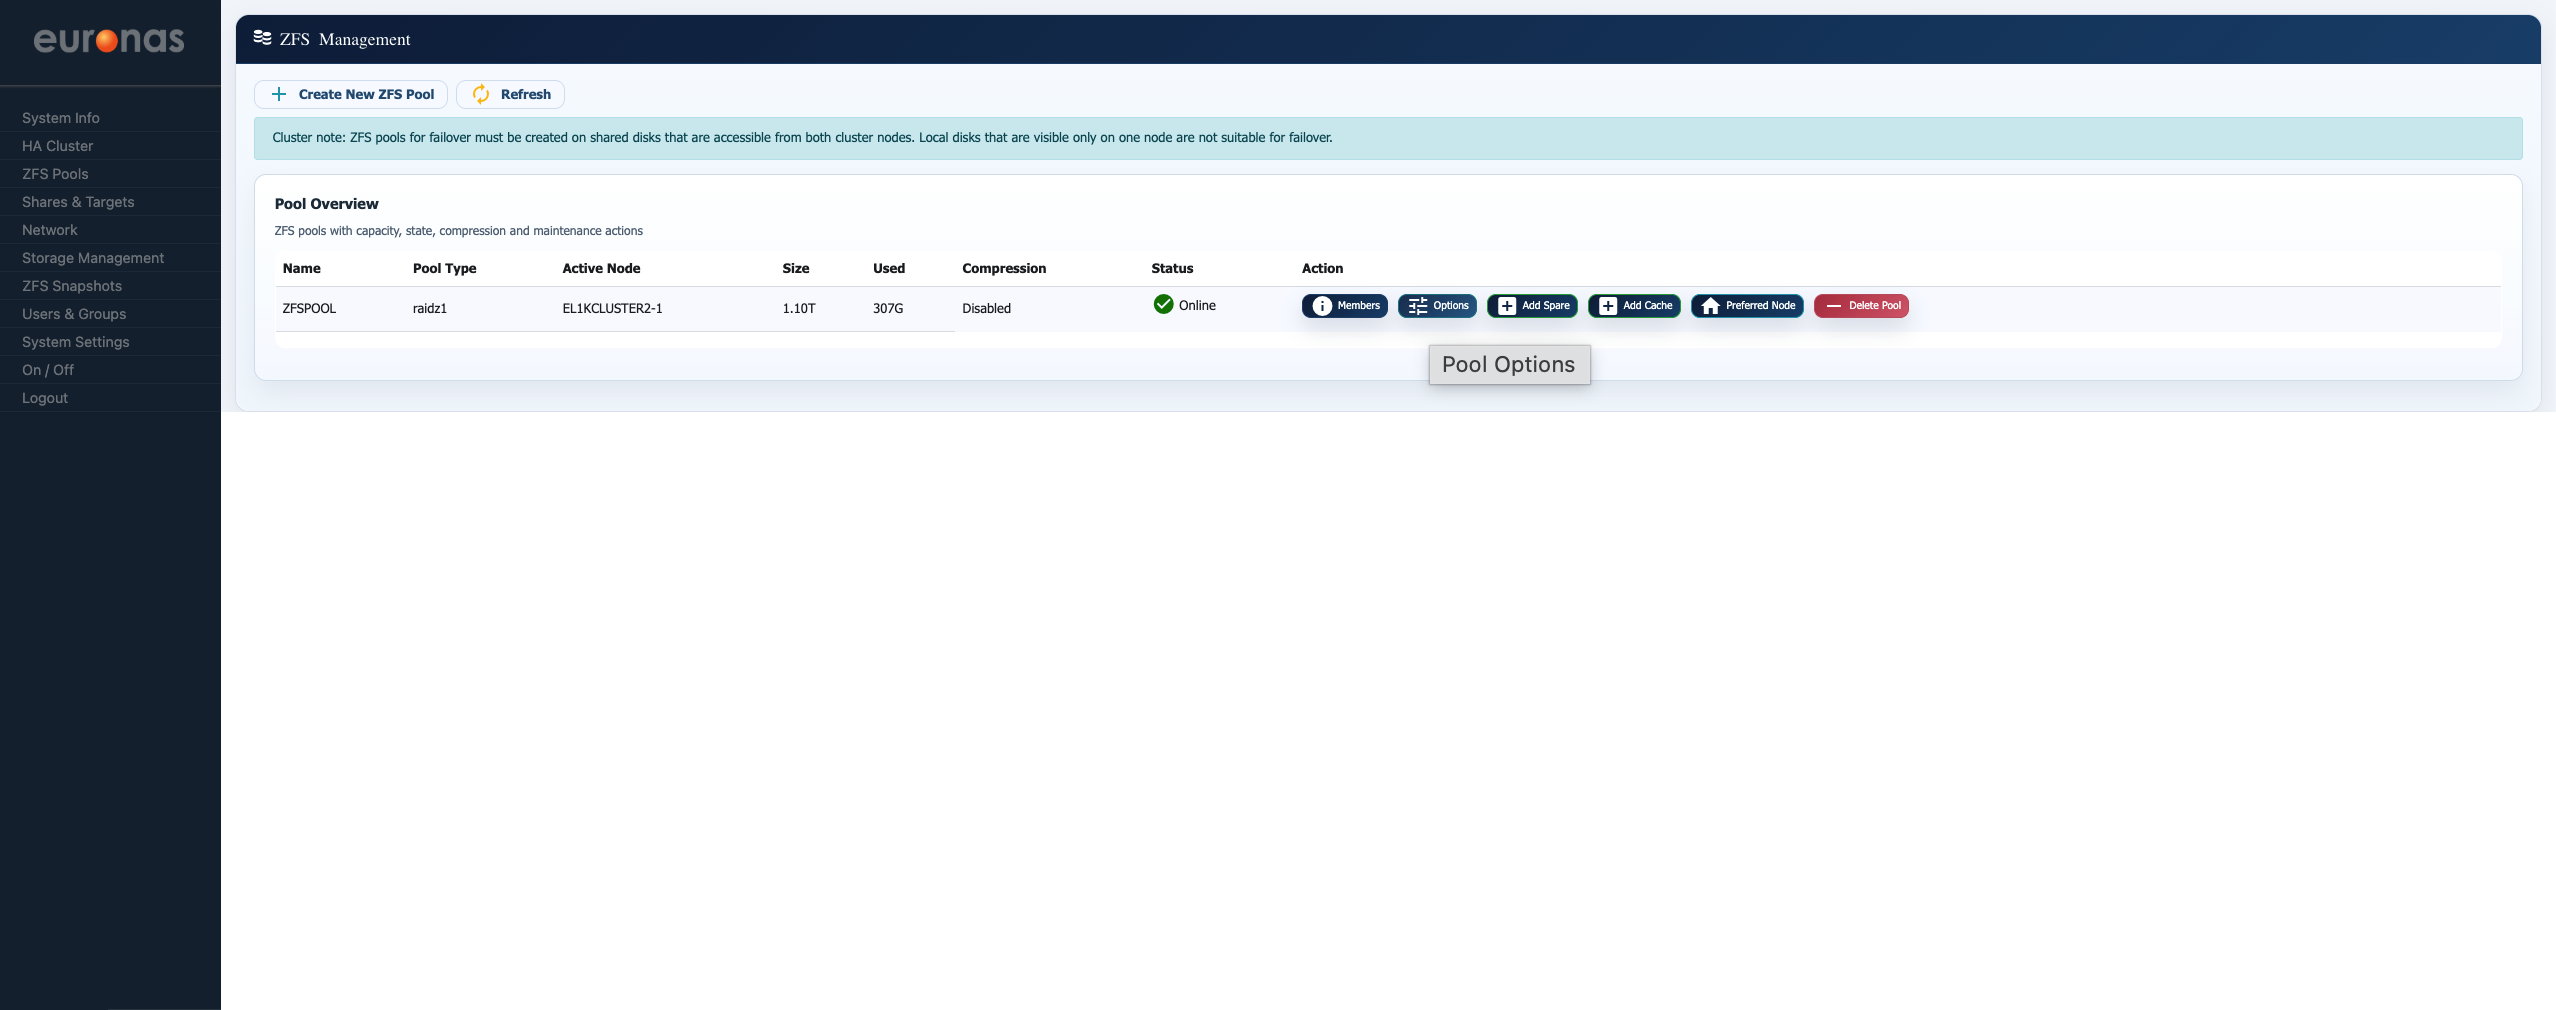
From the ZFS Management screen, select the Options button.
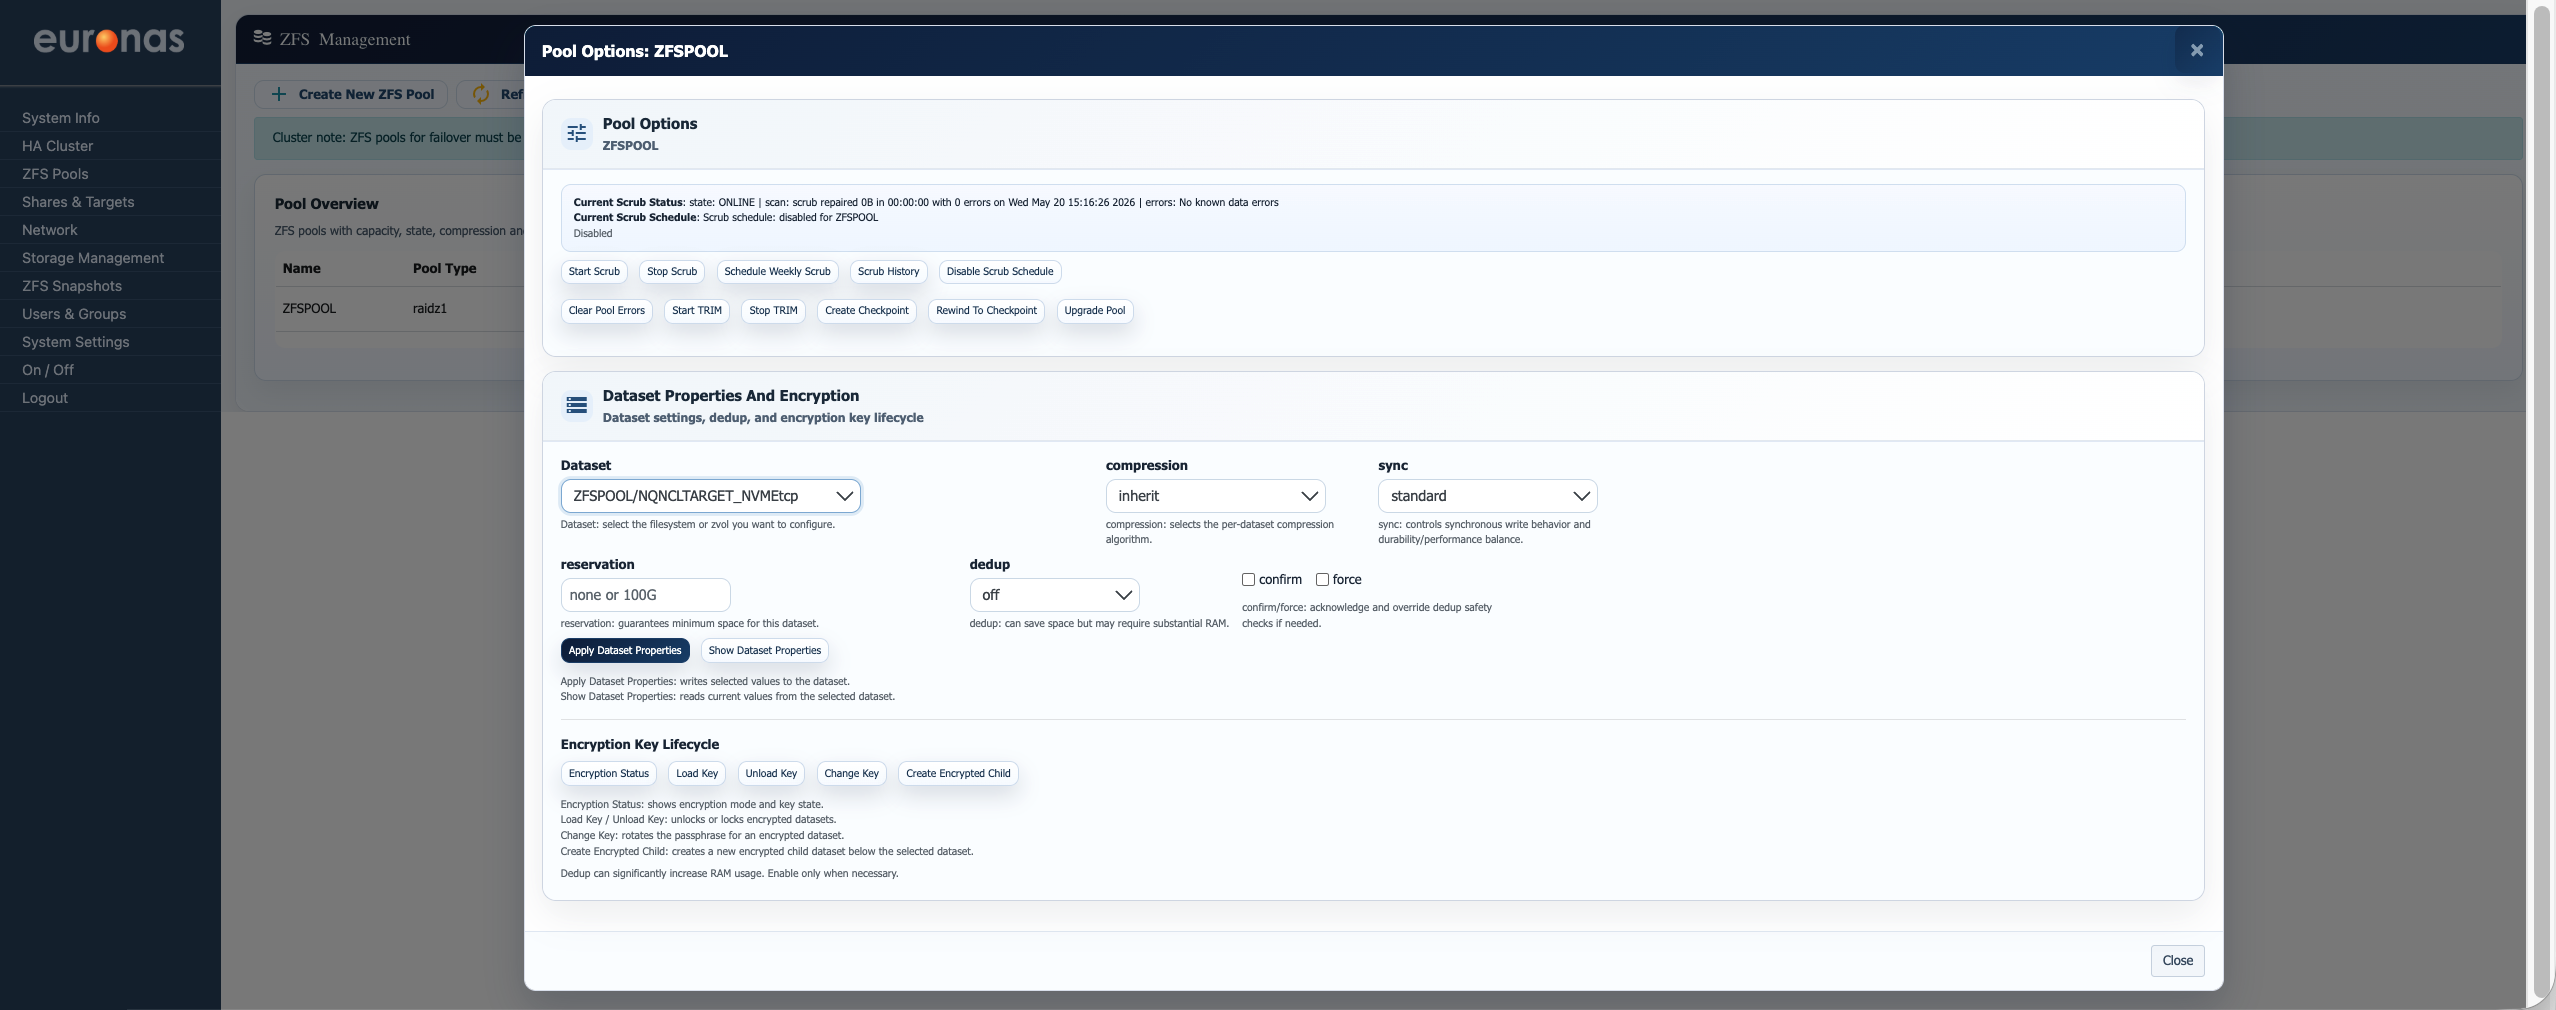
This will open the Pool Options screen, allowing administrators to manage pool dataset properties, compression, deduplication, synchronisation behaviour, and encryption settings for the selected ZFS pool.
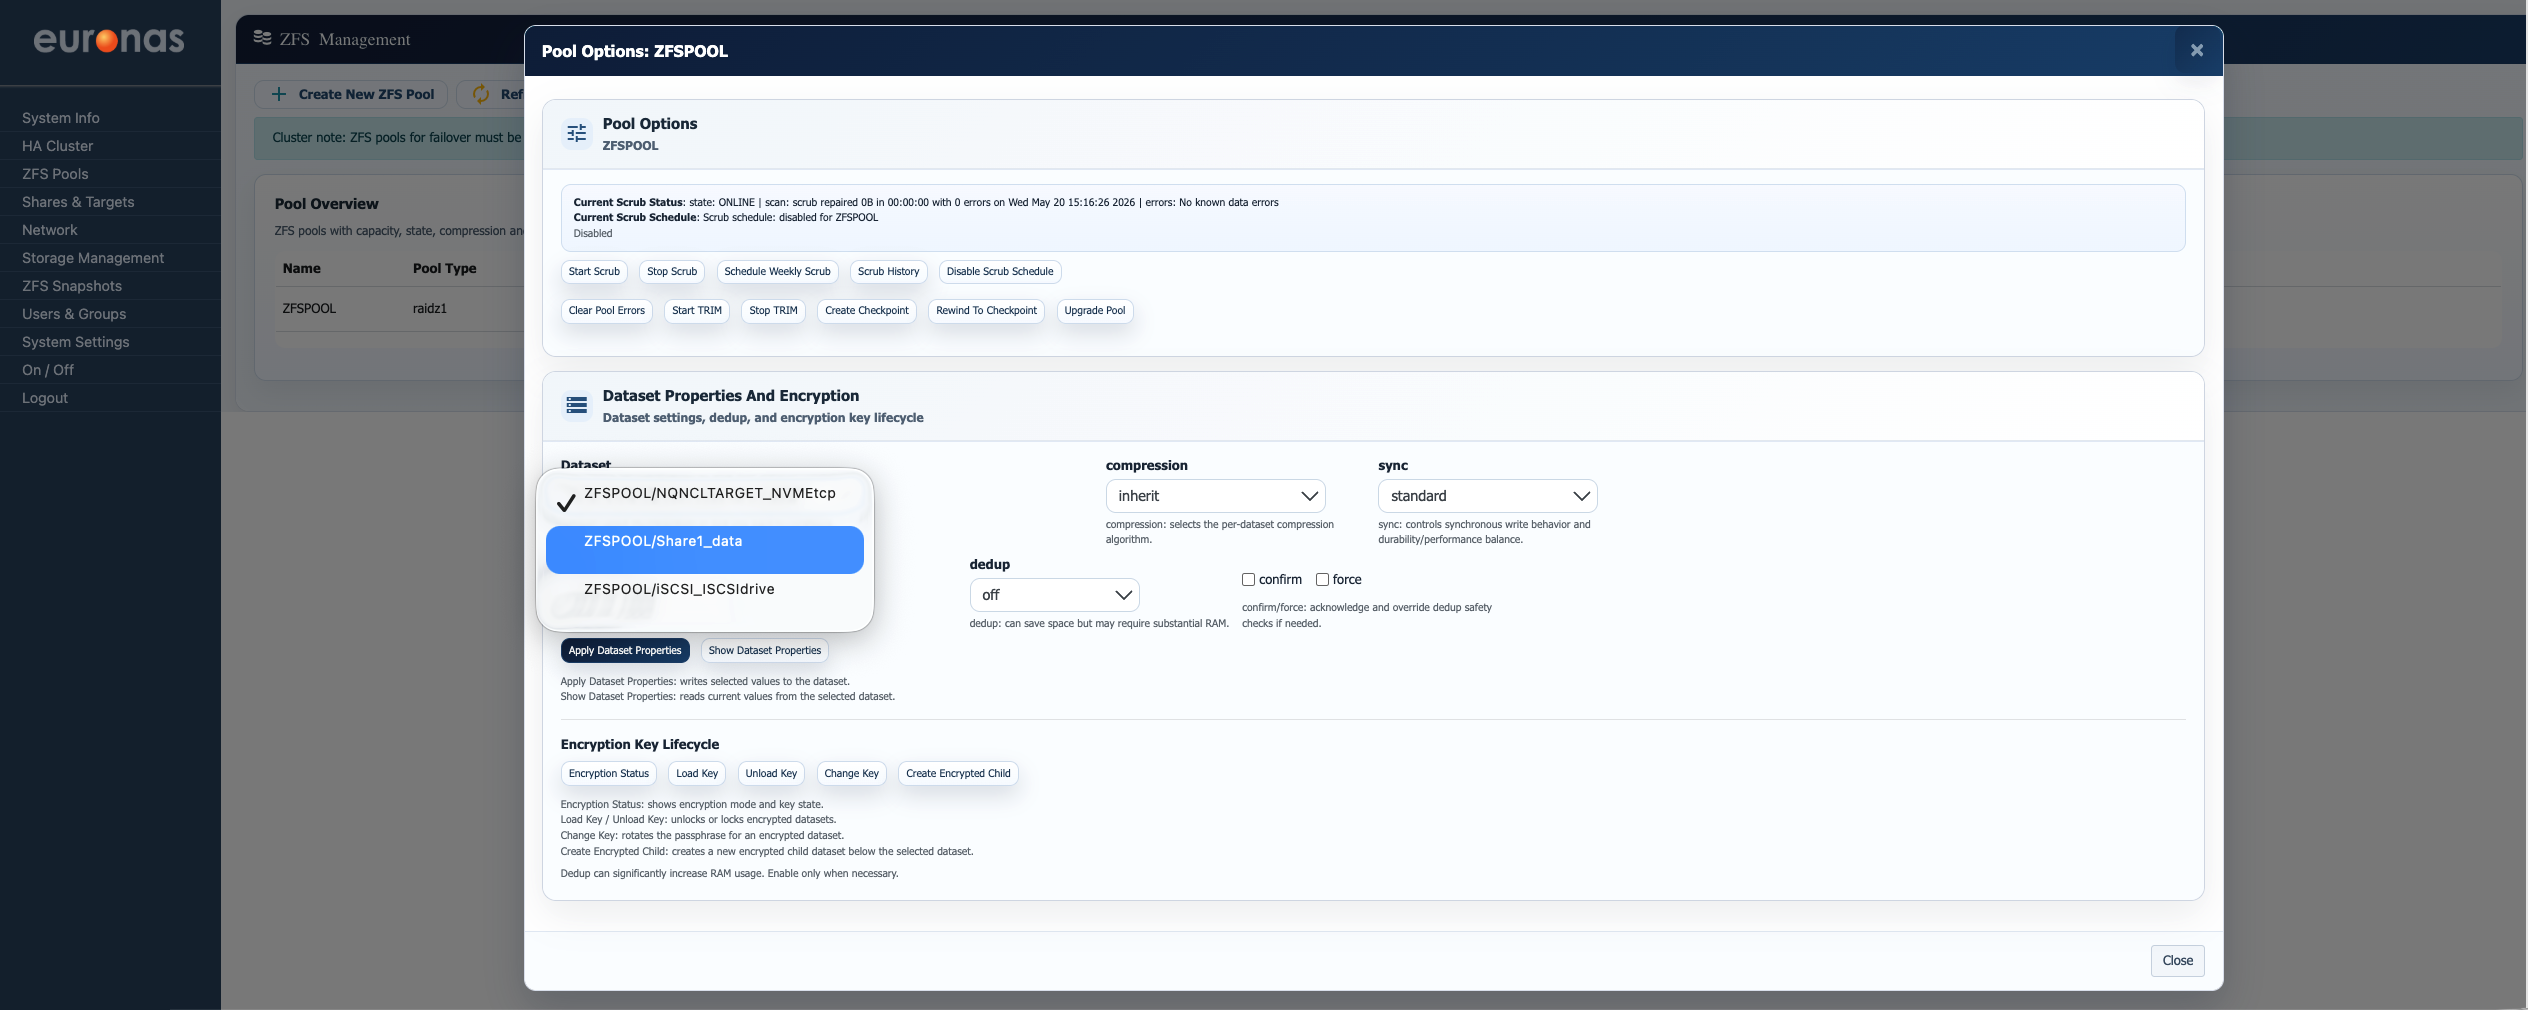
From the Dataset drop-down on the left-hand side of the screen, select the dataset you wish to configure. In this example, we will configure the ZFSPOOL/Share1_data dataset.
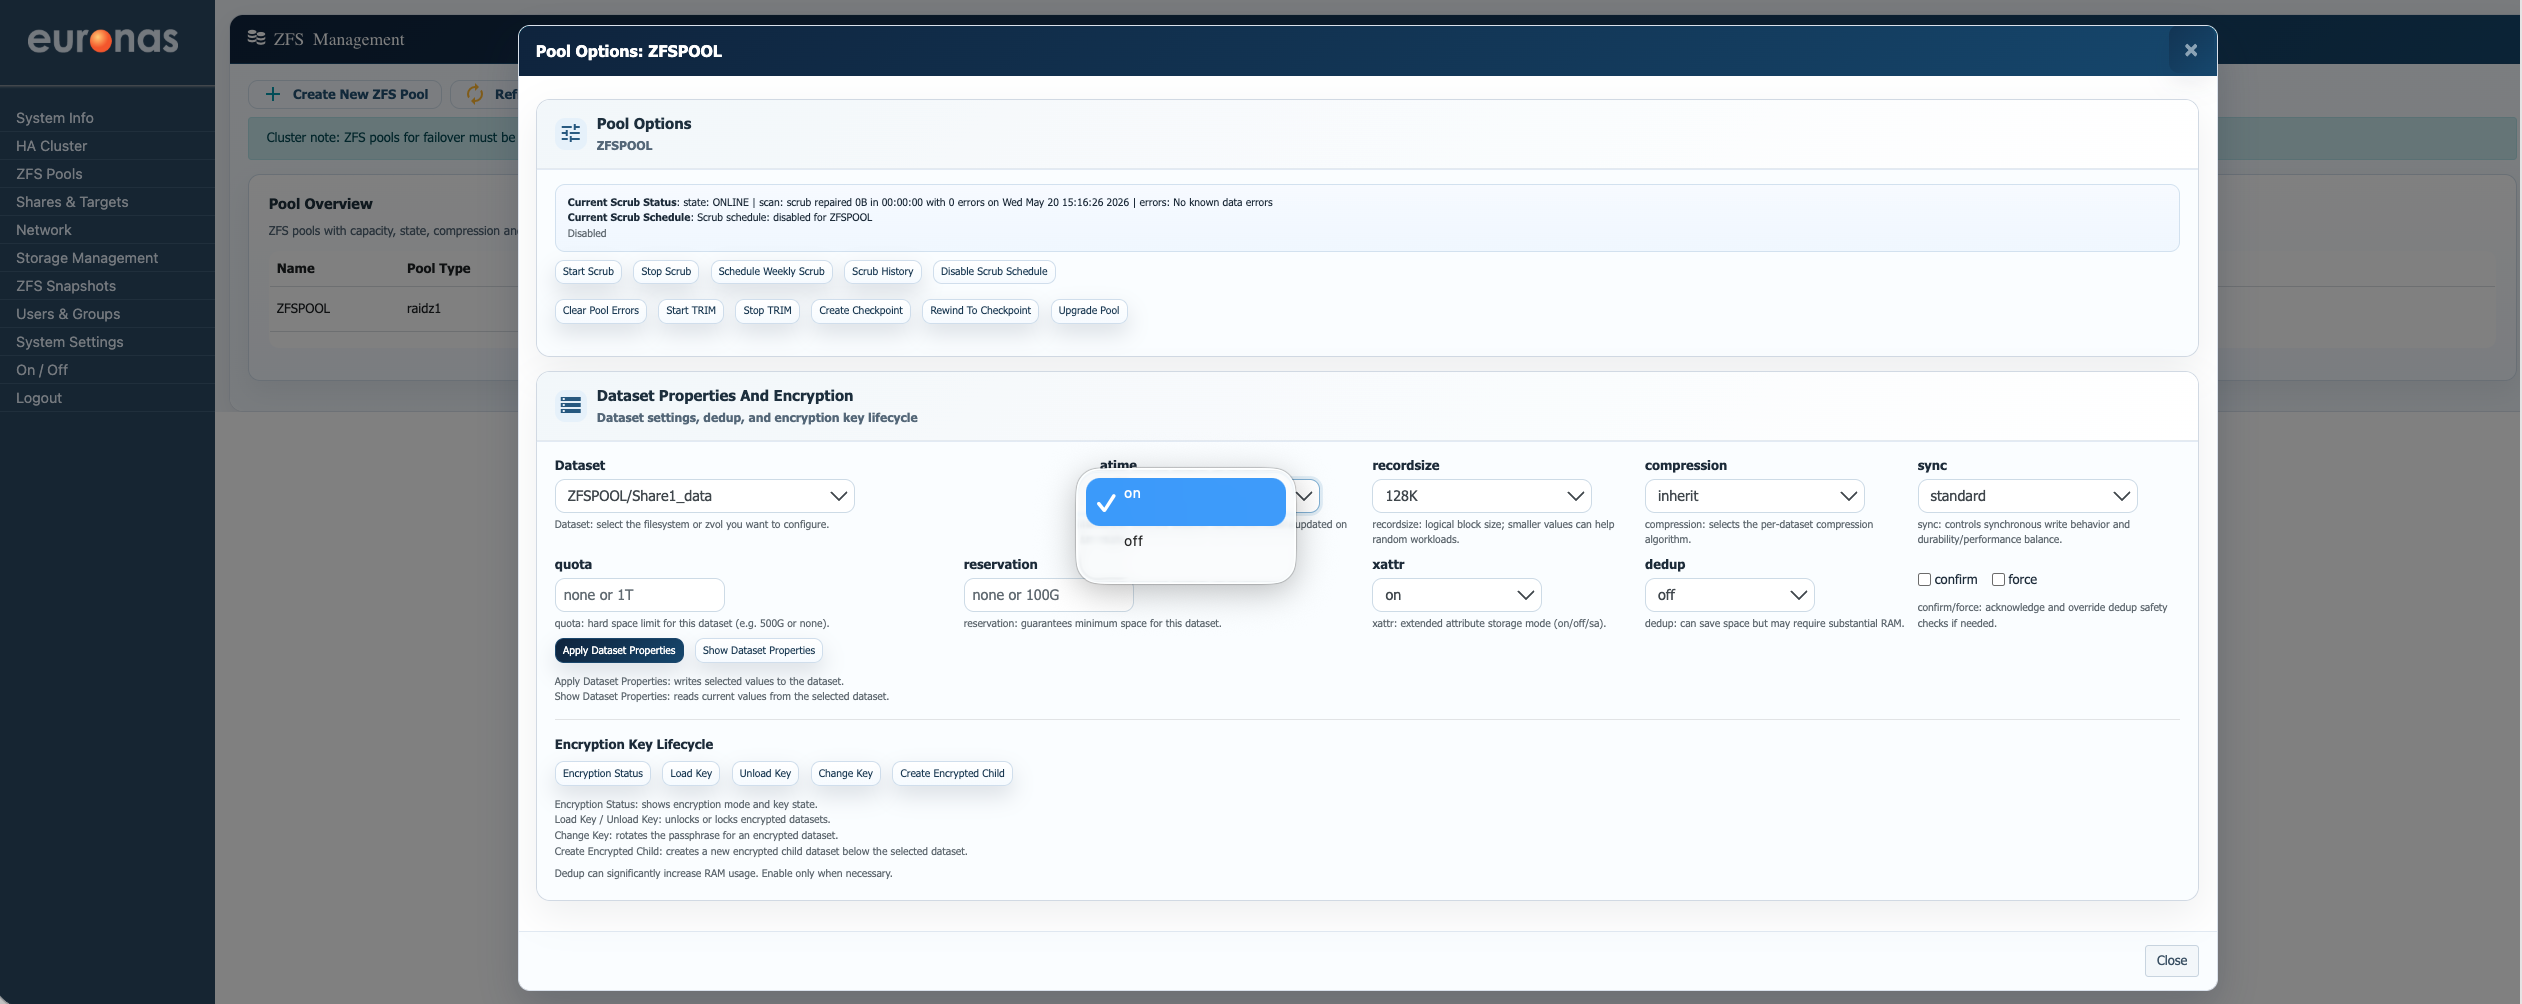
The atime setting controls whether ZFS updates the file access timestamp every time a file is read. While this may appear to be a small setting, it can have a noticeable impact on both performance and application behaviour depending on the workload.
When atime is enabled (on), ZFS records the last time a file was accessed. Some backup, archive, and data lifecycle management platforms rely on this information to determine whether files are still active, when they were last referenced, or whether data should be moved, retained, or expired. Disabling atime in these environments can interfere with retention logic, reporting accuracy, or automated data management policies.
In contrast, workloads such as virtual machine storage, media repositories, or high-performance application datasets often gain little value from access-time tracking. In these cases, disabling atime (off) can reduce unnecessary metadata updates and lower background disk activity caused by constant file reads.
Understanding the workload is therefore important before changing this setting. A configuration that improves performance for one application may negatively affect the operational behaviour of another. If in doubt, euroNAS recommends discussing the intended workload and dataset design with the support team prior to making production changes. Please contact support@euronas.com for guidance.
The recordsize setting is one of the most important ZFS tuning parameters as it controls the maximum block size used when storing data within the dataset. Selecting the correct value can have a major impact on performance, latency, fragmentation behaviour, compression efficiency, backup performance, and overall storage efficiency.
ZFS writes data in blocks, and the recordsize value determines how large those blocks can become. Larger record sizes reduce metadata overhead and generally improve sequential throughput, while smaller record sizes can improve responsiveness for random workloads by reducing read and write amplification.
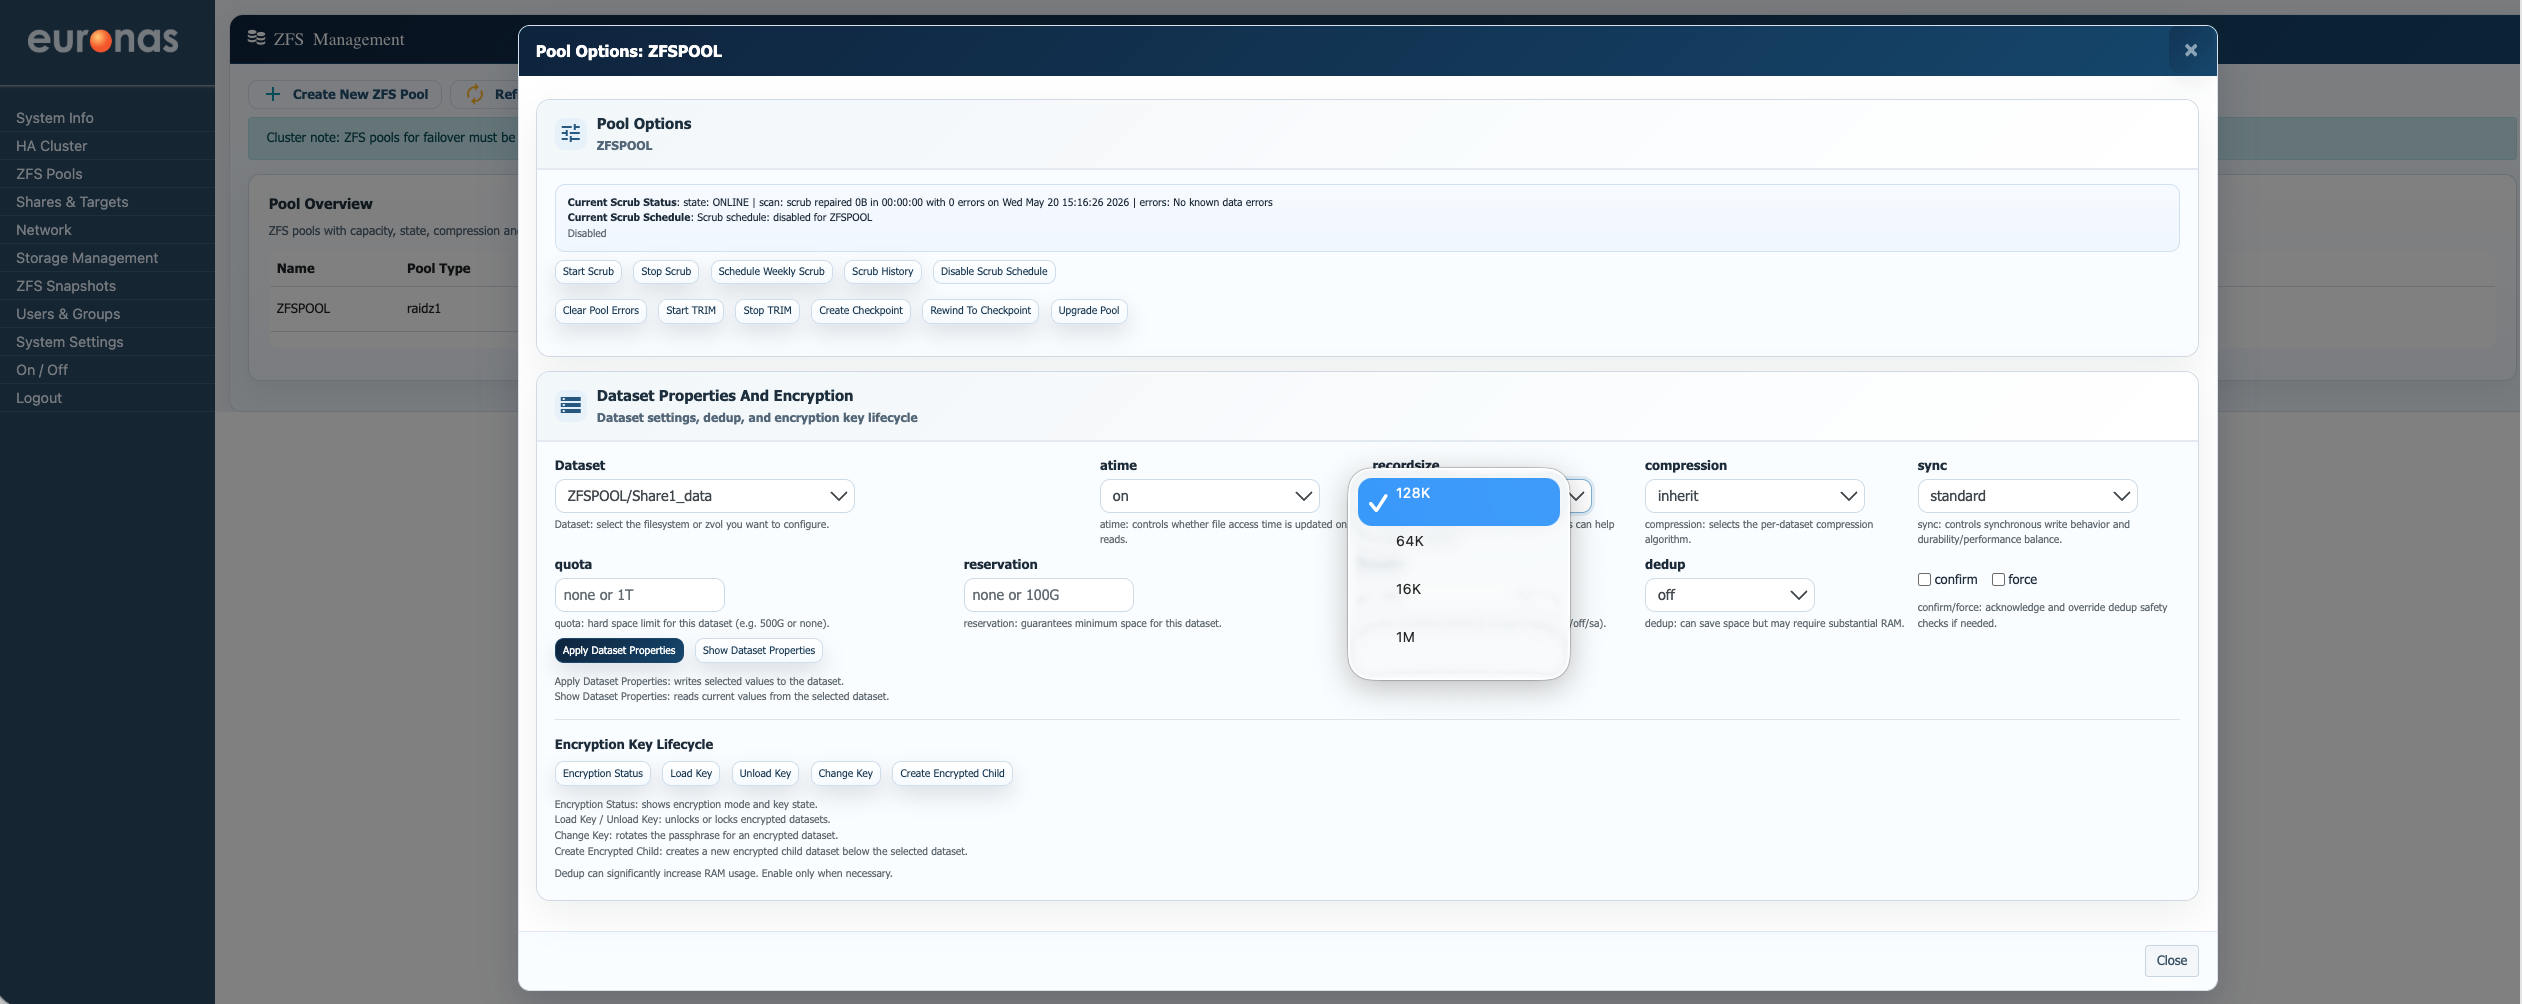
The available values shown here are:
- 16K – Typically used for highly random workloads such as databases or small-block transactional applications. Smaller records reduce the amount of unnecessary data read or rewritten during random I/O operations.
- 64K – Often used as a balanced middle ground for mixed workloads where data patterns are less predictable.
- 128K – The default and most common general-purpose setting for file shares, virtual machine storage, and standard application workloads. It provides a strong balance between throughput, metadata overhead, and compression efficiency.
- 1M – Optimised for large sequential workloads such as backup repositories, media archives, surveillance storage, or large object storage datasets. Larger record sizes allow ZFS to move significantly more data per operation with lower metadata overhead and improved compression ratios.
This setting becomes particularly important for backup workloads. Modern backup applications often write very large sequential streams of data, and using a small record size in these environments can dramatically increase fragmentation, metadata activity, and unnecessary I/O overhead. In contrast, larger record sizes such as 1M can substantially improve ingest performance, sequential read throughput, and storage efficiency for backup repositories.
However, incorrectly using very large record sizes on random-access workloads such as databases or VM boot volumes can negatively affect latency and increase write amplification, as small changes may require larger blocks to be rewritten.
Because recordsize directly affects how data is physically laid out on disk, changing it on an active dataset does not immediately rewrite existing data. The new setting only applies to newly written blocks going forward.
Understanding the application workload before changing this setting is therefore critical. If in doubt, euroNAS recommends discussing dataset tuning and workload design with the support team before making production changes.
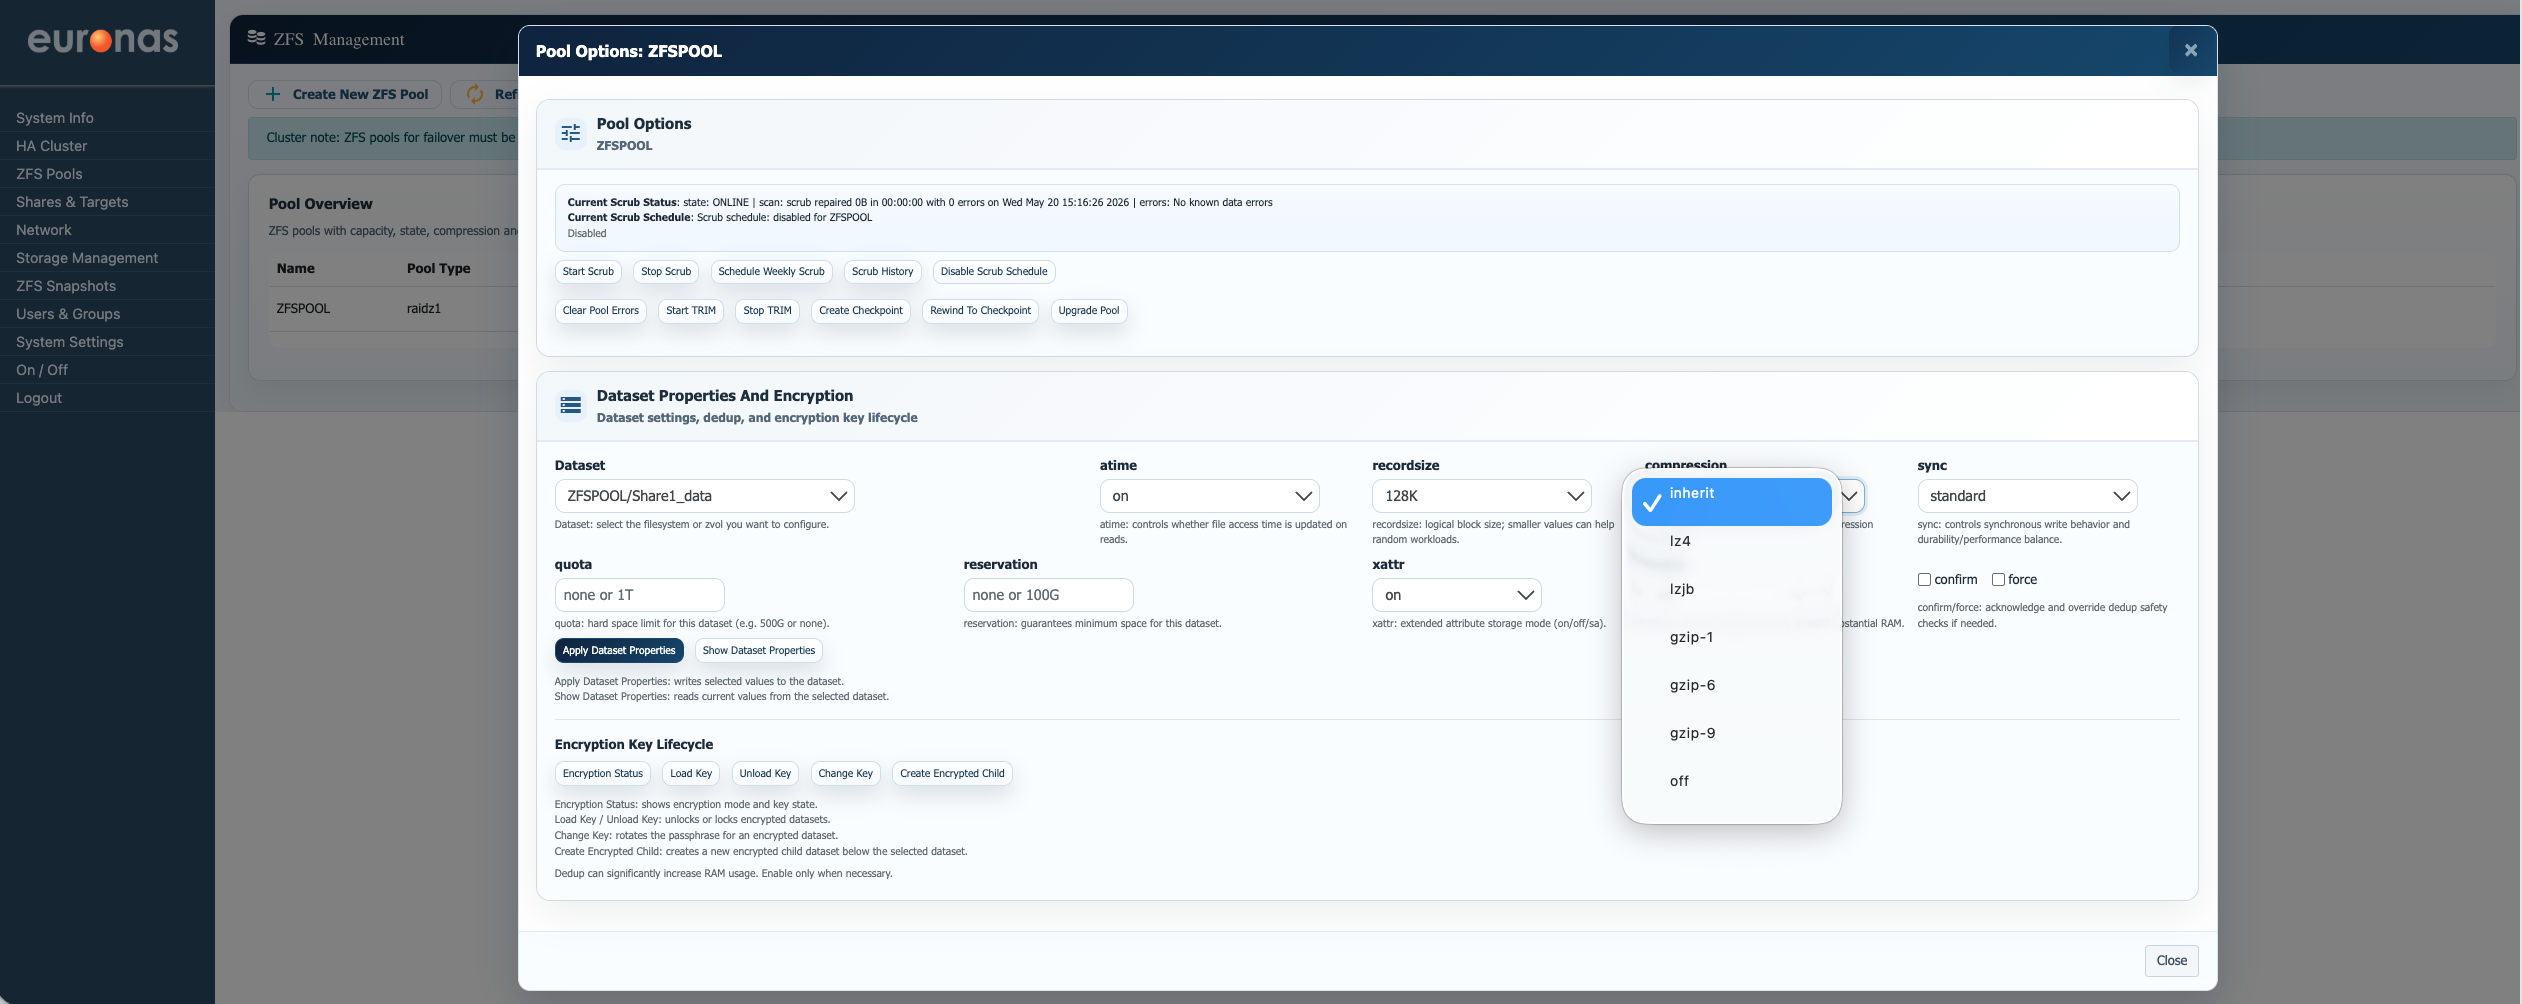
The Compression setting controls how ZFS compresses data written to the selected dataset. Compression can significantly reduce storage consumption and, in many cases, improve performance by reducing the amount of physical data written to disk.
The available options are:
- inherit – Uses the compression setting inherited from the parent pool or dataset. This is the default behaviour unless specifically overridden.
- lz4 – The recommended general-purpose compression algorithm for most workloads. It provides very fast compression and decompression with minimal CPU overhead and is suitable for virtual machines, file shares, and general application data.
- lzjb – An older lightweight compression method with lower compression efficiency than
lz4. Generally retained for legacy compatibility. - gzip-1 / gzip-6 / gzip-9 – Higher compression algorithms offering increasing levels of compression at the cost of additional CPU usage.
gzip-1provides lighter compression with lower CPU overhead.gzip-6offers a balance between compression ratio and CPU usage.gzip-9provides maximum compression but can significantly impact performance on busy systems.
- off – Disables compression entirely for the selected dataset. This may be useful for already compressed data such as media files, encrypted backups, or workloads where CPU overhead must be minimised.
For most deployments, lz4 is the recommended option due to its strong balance of performance and storage efficiency.